0%

Tianshou

source:Tianshou–强化学习算法框架学习笔记 - 知乎 (zhihu.com)

Cheat Sheet — Tianshou 0.5.1 documentation

欢迎查看天授平台中文文档 — 天授 0.4.6.post1 文档 (tianshou.readthedocs.io)

一、Tianshou的基本框架

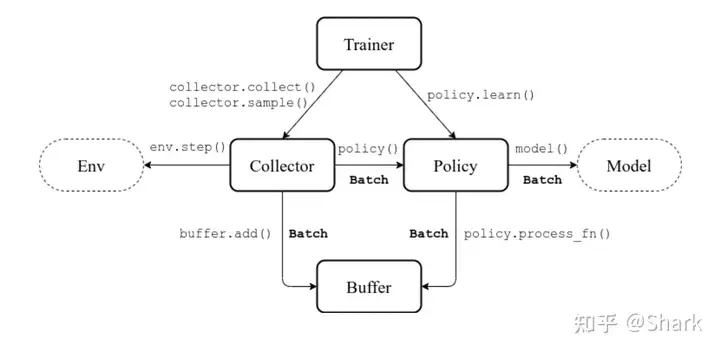
天授(Tianshou)把一个RL训练流程划分成了几个子模块:trainer(负责训练逻辑)、collector(负责数据采集)、policy(负责训练策略)和 buffer(负责数据存储),此外还有两个外围的模块,一个是env,一个是model(policy负责RL算法实现比如loss function的计算,model就只是个正常的神经网络)。下图描述了这些模块的依赖:
https://pic2.zhimg.com/80/v2-da45fbece6e91c073061d6b0b82ae50d_720w.webp

例子:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
import gymnasium as gym
import numpy as np
import tianshou as ts
import torch
from torch import nn
from torch.utils.tensorboard import SummaryWriter
from tianshou.utils import TensorboardLogger
​
​
class Net(nn.Module):
def __init__(self, state_shape, action_shape):
super().__init__()
self.model = nn.Sequential(
nn.Linear(np.prod(state_shape), 128), nn.ReLU(inplace=True),
nn.Linear(128, 128), nn.ReLU(inplace=True),
nn.Linear(128, np.prod(action_shape)),
)
​
def forward(self, obs, state=None, info={}):
if not isinstance(obs, torch.Tensor):
obs = torch.tensor(obs, dtype=torch.float)
batch = obs.shape[0]
logits = self.model(obs.view(batch, -1))
return logits, state
​
​
# Make an environment
env = gym.make('CartPole-v1')
state_shape = env.observation_space.shape[0]
action_shape = env.action_space.n
​
# Build the Network
net = Net(state_shape, action_shape)
optim = torch.optim.Adam(net.parameters(), lr=1e-3)
​
# Setup Policy
policy = ts.policy.DQNPolicy(net, optim, discount_factor=0.9, estimation_step=3, target_update_freq=320)
​
# Setup Collector
train_collector = ts.data.Collector(policy, env, ts.data.ReplayBuffer(20000, 10), exploration_noise=True)
test_collector = ts.data.Collector(policy, env, exploration_noise=True)
​
# logging
# writer = SummaryWriter('log/dqn')
# logger = TensorboardLogger(writer)
​
# Train Policy with a Trainer
result = ts.trainer.offpolicy_trainer(
policy, train_collector, test_collector,
max_epoch=10, step_per_epoch=10000, step_per_collect=10,
update_per_step=0.1, episode_per_test=100, batch_size=64,
train_fn=lambda epoch, env_step: policy.set_eps(0.1),
test_fn=lambda epoch, env_step: policy.set_eps(0.05),
stop_fn=lambda mean_rewards: mean_rewards >= env.spec.reward_threshold)
print(f'Finished training! Use {result["duration"]}')

下面,我们就将一步一步的了解上图中所有的API,对Tianshou有一个大致的了解。

二、Batch

下面我们首先来看看Batch这个数据结构:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
import numpy as np
from tianshou.data import Batch
data = Batch(a=4, b=[5, 5], c='2312312', d=('a', -2, -3))
print(data)
print(data.b)
​
"""
Batch(
a: array(4),
b: array([5, 5]),
c: '2312312',
d: array(['a', '-2', '-3'], dtype=object),
)
[5 5]
"""

可以发现,batch类似于dict,存储key-value对,并且可以自动将value转化成numpy array。

下面例子演示Batch存储numpy和pytorch的数据:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
import torch
batch1 = Batch(a=np.arange(2), b=torch.zeros((2,2)))
batch2 = Batch(a=np.arange(2), b=torch.ones((2,2)))
batch_cat = Batch.cat([batch1, batch2, batch1])
print(batch1)
print(batch2)
print(batch_cat)
"""
Batch(
a: array([0, 1]),
b: tensor([[0., 0.],
[0., 0.]]),
)
Batch(
a: array([0, 1]),
b: tensor([[1., 1.],
[1., 1.]]),
)
Batch(
b: tensor([[0., 0.],
[0., 0.],
[1., 1.],
[1., 1.],
[0., 0.],
[0., 0.]]),
a: array([0, 1, 0, 1, 0, 1]),
)
"""

将Batch中的数据类型统一转换成numpy或pytorch的数据类型:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
batch_cat.to_numpy()
print(batch_cat)
batch_cat.to_torch()
print(batch_cat)
"""
Batch(
a: array([0, 1, 0, 1, 0, 1]),
b: array([[0., 0.],
[0., 0.],
[1., 1.],
[1., 1.],
[0., 0.],
[0., 0.]], dtype=float32),
)
Batch(
a: tensor([0, 1, 0, 1, 0, 1]),
b: tensor([[0., 0.],
[0., 0.],
[1., 1.],
[1., 1.],
[0., 0.],
[0., 0.]]),
)
"""

三、ReplayBuffer

Replay buffer在RL的off-policy中非常常用,其可以存储过去的经验,以便训练我们的agent。

在Tianshou中,可以把replay buffer看成一种特殊的Batch。

下面是使用replay buffer的例子:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
from tianshou.data import Batch, ReplayBuffer
​
# a buffer is initialised with its maxsize set to 10 (older data will be discarded if more data flow in).
print("========================================")
buf = ReplayBuffer(size=10)
print(buf)
print("maxsize: {}, data length: {}".format(buf.maxsize, len(buf)))
​
# add 3 steps of data into ReplayBuffer sequentially
print("========================================")
for i in range(3):
buf.add(Batch(obs=i, act=i, rew=i, done=0, obs_next=i + 1, info={}))
print(buf)
print("maxsize: {}, data length: {}".format(buf.maxsize, len(buf)))
​
# add another 10 steps of data into ReplayBuffer sequentially
print("========================================")
for i in range(3, 13):
buf.add(Batch(obs=i, act=i, rew=i, done=0, obs_next=i + 1, info={}))
print(buf)
print("maxsize: {}, data length: {}".format(buf.maxsize, len(buf)))
"""
========================================
ReplayBuffer()
maxsize: 10, data length: 0
========================================
ReplayBuffer(
info: Batch(),
obs_next: array([1, 2, 3, 0, 0, 0, 0, 0, 0, 0]),
act: array([0, 1, 2, 0, 0, 0, 0, 0, 0, 0]),
obs: array([0, 1, 2, 0, 0, 0, 0, 0, 0, 0]),
done: array([False, False, False, False, False, False, False, False, False,
False]),
rew: array([0., 1., 2., 0., 0., 0., 0., 0., 0., 0.]),
)
maxsize: 10, data length: 3
========================================
ReplayBuffer(
info: Batch(),
obs_next: array([11, 12, 13, 4, 5, 6, 7, 8, 9, 10]),
act: array([10, 11, 12, 3, 4, 5, 6, 7, 8, 9]),
obs: array([10, 11, 12, 3, 4, 5, 6, 7, 8, 9]),
done: array([False, False, False, False, False, False, False, False, False,
False]),
rew: array([10., 11., 12., 3., 4., 5., 6., 7., 8., 9.]),
)
maxsize: 10, data length: 10
"""

replay buffer中保留了七个属性,Tianshou推荐我们使用这七个推荐的属性,而不是自己去创建其他属性。
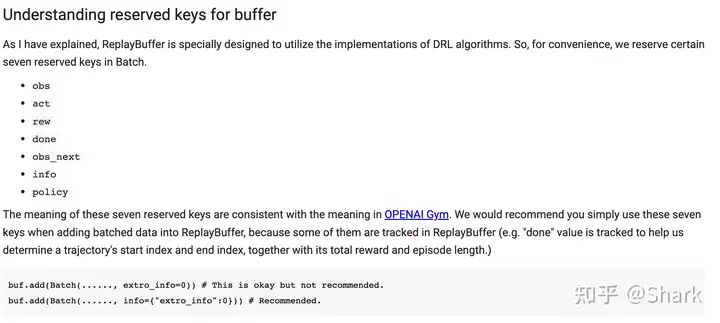
我们也看到了,buffer其实就是一种特殊的Batch,那他存在的意义是什么呢?

就在于可以从buffer中sample数据给到collector中,供agent进行训练。

现在Tianshou支持gymnasium,所以又多了两个属性:truncated和terminated。

我们还可以高效的从buffer中追踪trajectory信息。

下面这段代码可以获得下标为6的step所处的episode的第一个step的下标

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
# Search for the previous index of index "6"
now_index = 6
while True:
prev_index = buf.prev(now_index)
print(prev_index)
if prev_index == now_index:
break
else:
now_index = prev_index
"""
5
4
3
3
"""

同理,下面代码可以返回在当前episode中下一个step的下标:

1
2
3
4
5
6
7
# next step of indexes [4,5,6,7,8,9] are:
print(buf.next([4,5,6,7,8,9]))
print(buf.next(7))
"""
[5 6 7 7 9 0]
7
"""

这在n-step-return的时候非常有用(n-step TD)

四、Vectorized Environment
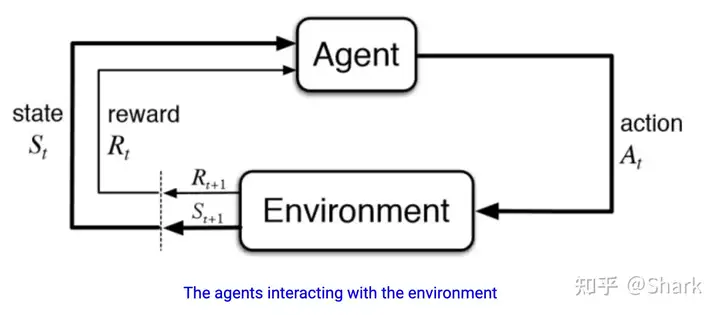
在gym中,环境接收一个动作,返回下一个状态的观测和奖励。这个过程很慢,并且常常是实验的性能瓶颈,所以Tianshou利用并行环境加速这一过程。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
from tianshou.env import SubprocVectorEnv
import numpy as np
import gym
import time
​
num_cpus = [1,2,5]
for num_cpu in num_cpus:
# SubprocVectorEnv这个wrapper利用多个进程,并行执行多个环境。
env = SubprocVectorEnv([lambda: gym.make('CartPole-v0') for _ in range(num_cpu)])
env.reset()
sampled_steps = 0
time_start = time.time()
while sampled_steps < 1000:
act = np.random.choice(2, size=num_cpu)
obs, rew, done, info = env.step(act)
if np.sum(done):
env.reset(np.where(done)[0])
sampled_steps += num_cpu
time_used = time.time() - time_start
print("{}s used to sample 1000 steps if using {} cpus.".format(time_used, num_cpu))

下面是单个环境与多个环境的对比:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
from tianshou.env import DummyVectorEnv
# In Gym
env = gym.make("CartPole-v0")
​
# In Tianshou
def helper_function():
env = gym.make("CartPole-v0")
# other operations such as env.seed(np.random.choice(10))
return env
​
envs = DummyVectorEnv([helper_function for _ in range(5)])
​
# In Gym, env.reset() returns a single observation.
print("In Gym, env.reset() returns a single observation.")
print(env.reset())
​
# In Tianshou, envs.reset() returns stacked observations.
print("========================================")
print("In Tianshou, envs.reset() returns stacked observations.")
print(envs.reset())
​
obs, rew, done, info = envs.step(np.random.choice(2, size=num_cpu))
print(info)
"""
In Gym, env.reset() returns a single observation.
[0.04703292 0.03945684 0.03802961 0.02598534]
========================================
In Tianshou, envs.reset() returns stacked observations.
[[ 0.04029649 -0.01946092 -0.02980652 -0.01614117]
[-0.03085166 -0.04178732 -0.02325586 0.00156881]
[ 0.00672287 0.04306572 0.01217845 -0.04455359]
[ 0.03829754 0.02683093 -0.01153483 0.04290532]
[ 0.04420044 0.00097068 -0.01117315 0.04102308]]
[{'env_id': 0} {'env_id': 1} {'env_id': 2} {'env_id': 3} {'env_id': 4}]
"""

五、Policy

Policy就是agent如何做出action的\pi函数。

所有Policy模块都继承自BasePolicy类,并且具有相同的接口。

下面我们就来看看如何实现一个简单的REINFORCE的policy。

1
2
3
4
5
6
7
8
9
10
11
12
from typing import Any, Dict, List, Optional, Type, Union
​
import numpy as np
import torch
​
from tianshou.data import Batch, ReplayBuffer, to_torch, to_torch_as
from tianshou.policy import BasePolicy
​
class REINFORCEPolicy(BasePolicy):
"""Implementation of REINFORCE algorithm."""
def __init__(self):
super().__init__()

policy最重要的两个功能就是

  1. 选择动作(forward)
  2. 更新参数(update),update先调用process_fn函数,处理从buffer来的数据;然后调用learn,反向传播,更新参数。
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
from typing import Any, Dict, List, Optional, Type, Union
​
import numpy as np
import torch
​
from tianshou.data import Batch, ReplayBuffer, to_torch, to_torch_as
from tianshou.policy import BasePolicy
​
​
class REINFORCEPolicy(BasePolicy):
"""Implementation of REINFORCE algorithm."""
def __init__(self, model: torch.nn.Module, optim: torch.optim.Optimizer,):
super().__init__()
self.actor = model
self.optim = optim
​
def forward(self, batch: Batch) -> Batch:
"""Compute action over the given batch data."""
act = None
return Batch(act=act)
​
def process_fn(self, batch: Batch, buffer: ReplayBuffer, indices: np.ndarray) -> Batch:
"""Compute the discounted returns for each transition."""
pass
​
def learn(self, batch: Batch, batch_size: int, repeat: int) -> Dict[str, List[float]]:
"""Perform the back-propagation."""
return

六、Collector

collector与policy和环境交互,在其内部,把envs和buffer有机的结合起来,封装了其中的数据交互。
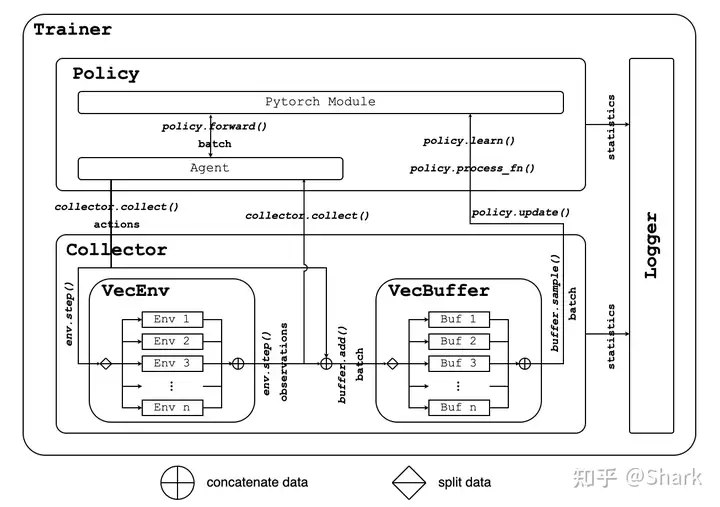
Collector在训练(收集数据)时和评估策略时都可以使用。

Data Collecting:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
from tianshou.data import VectorReplayBuffer
​
train_env_num = 4
buffer_size = 100
train_envs = DummyVectorEnv([lambda: gym.make("CartPole-v0") for _ in range(train_env_num)])
replaybuffer = VectorReplayBuffer(buffer_size, train_env_num)
​
# 定义一个Collector
train_collector = Collector(policy, train_envs, replaybuffer)
​
# 利用Collector收集50个step的数据,自动存入replaybuffer中
collect_result = train_collector.collect(n_step=50)
​
# 下面我们可以从buffer中抽样数据
replaybuffer.sample(10)

Policy evaluation:

我们已经有了一个policy,现在我们想评估一下这个policy,看看reward情况等等。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
import gym
import numpy as np
import torch
​
from tianshou.data import Collector
from tianshou.env import DummyVectorEnv
from tianshou.policy import PGPolicy
from tianshou.utils.net.common import Net
from tianshou.utils.net.discrete import Actor
​
import warnings
warnings.filterwarnings('ignore')
​
env = gym.make("CartPole-v0")
test_envs = DummyVectorEnv([lambda: gym.make("CartPole-v0") for _ in range(2)])
​
# model
net = Net(env.observation_space.shape, hidden_sizes=[16,])
actor = Actor(net, env.action_space.shape)
optim = torch.optim.Adam(actor.parameters(), lr=0.0003)
​
policy = PGPolicy(actor, optim, dist_fn=torch.distributions.Categorical)
test_collector = Collector(policy, test_envs)
​
# 收集9个episode
collect_result = test_collector.collect(n_episode=9)
print(collect_result)
"""
{'n/ep': 9, 'n/st': 82, 'rews': array([ 9., 9., 9., 9., 8., 9., 9., 11., 9.]), 'lens': array([ 9, 9, 9, 9, 8, 9, 9, 11, 9]), 'idxs': array([0, 1, 0, 1, 0, 1, 0, 1, 0]), 'rew': 9.11111111111111, 'len': 9.11111111111111, 'rew_std': 0.7370277311900889, 'len_std': 0.7370277311900889}
"""
print("Rewards of 9 episodes are {}".format(collect_result["rews"]))
"""
Rewards of 9 episodes are [ 9. 9. 9. 9. 8. 9. 9. 11. 9.]
"""
print("Average episode reward is {}.".format(collect_result["rew"]))
"""
Average episode reward is 9.11111111111111.
"""
print("Average episode length is {}.".format(collect_result["len"]))
"""
Average episode length is 9.11111111111111.
"""

七、Trainer

Trainer是Tianshou中的顶层封装,它控制traning loop和对Policy的evaluation。Trainer控制Policy和Collector的交互。

Tianshou中包含三类Trainer:On-policy training, off-policy training, offline training.

下面是REINFORCE算法的整体流程(利用On-policy)。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
import gymnasium as gym
import numpy as np
import torch
​
from tianshou.data import Collector, VectorReplayBuffer
from tianshou.env import DummyVectorEnv
from tianshou.policy import PGPolicy
from tianshou.utils.net.common import Net
from tianshou.utils.net.discrete import Actor
​
import warnings
​
warnings.filterwarnings('ignore')
​
train_env_num = 4
buffer_size = 2000 # Since REINFORCE is an on-policy algorithm, we don't need a very large buffer size
​
# Create the environments, used for training and evaluation
env = gym.make("CartPole-v1")
test_envs = DummyVectorEnv([lambda: gym.make("CartPole-v1") for _ in range(2)])
train_envs = DummyVectorEnv([lambda: gym.make("CartPole-v1") for _ in range(train_env_num)])
​
# Create the Policy instance
net = Net(env.observation_space.shape, hidden_sizes=[16, ])
actor = Actor(net, env.action_space.shape)
optim = torch.optim.Adam(actor.parameters(), lr=0.001)
policy = PGPolicy(actor, optim, dist_fn=torch.distributions.Categorical)
​
# Create the replay buffer and the collector
replaybuffer = VectorReplayBuffer(buffer_size, train_env_num)
test_collector = Collector(policy, test_envs) # 可以发现,test_collector没有replaybuffer,因为不做训练,只是测试
train_collector = Collector(policy, train_envs, replaybuffer)
​
train_collector.reset()
train_envs.reset()
test_collector.reset()
test_envs.reset()
replaybuffer.reset()
for i in range(10): # 10 epoch
evaluation_result = test_collector.collect(n_episode=10) # test_collector用来测试当前policy,得出reward。
print("Evaluation reward is {}".format(evaluation_result["rew"]))
train_collector.collect(n_step=2000) # 收集2000个step到replaybuffer中
# 0 means taking all data stored in train_collector.buffer
policy.update(0, train_collector.buffer, batch_size=512, repeat=1) # buffer中所有数据,每次batch_size为512,
train_collector.reset_buffer(keep_statistics=True)
​
# 下面是使用tainer的代码:
train_collector.reset()
train_envs.reset()
test_collector.reset()
test_envs.reset()
replaybuffer.reset()
​
result = onpolicy_trainer(
policy,
train_collector,
test_collector,
max_epoch=10,
step_per_epoch=1, # 每个epoch进行多少次transitions
repeat_per_collect=1, # the number of repeat time for policy learning, for example, set it to 2 means the policy needs to learn each given batch data twice.
episode_per_test=10, # 每次测试进行几个episode
step_per_collect=2000, # 每次update前,收集多少step的数据
batch_size=512, # update的时候batch的大小
)
print(result)

可以发现,trainer就是包装了一下循环。

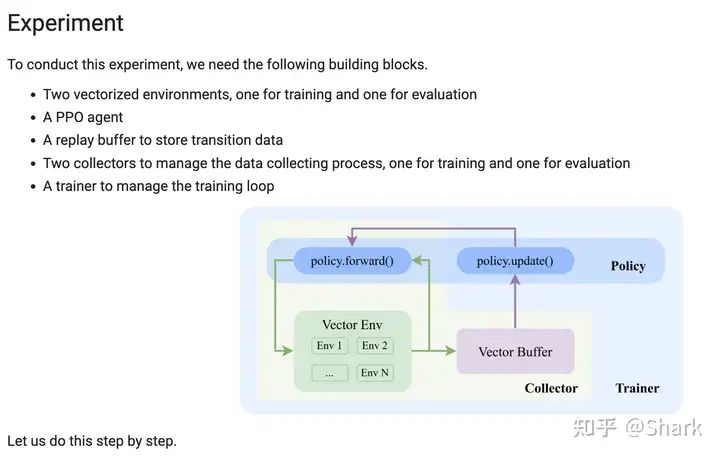
八、Experiment

这一节我们用PPO来解决CartPole
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
import gym
import numpy as np
import torch
​
from tianshou.data import Collector, VectorReplayBuffer
from tianshou.env import DummyVectorEnv
from tianshou.policy import PPOPolicy
from tianshou.trainer import onpolicy_trainer
from tianshou.utils.net.common import ActorCritic, Net
from tianshou.utils.net.discrete import Actor, Critic
​
import warnings
warnings.filterwarnings('ignore')
​
device = 'cuda' if torch.cuda.is_available() else 'cpu'
​
env = gym.make('CartPole-v0')
train_envs = DummyVectorEnv([lambda: gym.make('CartPole-v0') for _ in range(20)])
test_envs = DummyVectorEnv([lambda: gym.make('CartPole-v0') for _ in range(10)])
​
# net is the shared head of the actor and the critic
net = Net(env.observation_space.shape, hidden_sizes=[64, 64], device=device)
actor = Actor(net, env.action_space.n, device=device).to(device)
critic = Critic(net, device=device).to(device)
actor_critic = ActorCritic(actor, critic)
​
# optimizer of the actor and the critic
optim = torch.optim.Adam(actor_critic.parameters(), lr=0.0003)
​
dist = torch.distributions.Categorical
policy = PPOPolicy(actor, critic, optim, dist, action_space=env.action_space, deterministic_eval=True)
​
train_collector = Collector(policy, train_envs, VectorReplayBuffer(20000, len(train_envs)))
test_collector = Collector(policy, test_envs)
​
result = onpolicy_trainer(
policy,
train_collector,
test_collector,
max_epoch=10,
step_per_epoch=50000,
repeat_per_collect=10,
episode_per_test=10,
batch_size=256,
step_per_collect=2000,
stop_fn=lambda mean_reward: mean_reward >= 195,
)